Postgres vs. Redshift: When Each Database Wins (and When to Run Both)

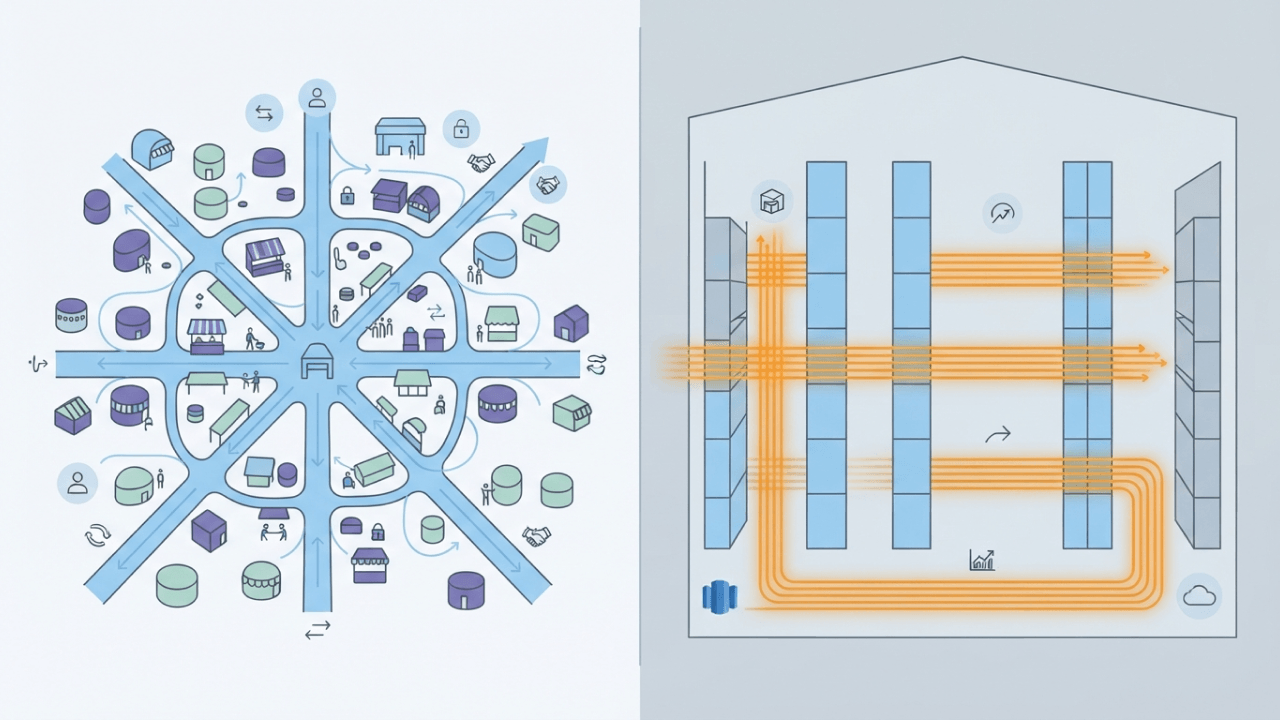
PostgreSQL excels at transactional workloads with indexed lookups. Redshift dominates large-scale analytical queries through columnar storage and parallel processing. This comparison covers the architectural tradeoffs, SQL compatibility gaps, and cost considerations that shape the decision, plus guidance on when running both systems together actually makes sense.
Key takeaways: Postgres vs Redshift
Postgres is a row-oriented transactional database that handles analytics well at smaller scales. Redshift is a columnar cloud data warehouse built specifically for massive analytical workloads. The right choice depends on your query patterns, data volume, and how much operational complexity your team can absorb.
Here are the core distinctions that drive this decision:
- Workload fit: Postgres excels at transactional workloads with concurrent reads, writes, and point lookups. Redshift excels at large aggregations across millions of rows.
- Scale threshold: Choose Postgres when your data fits on a single node and queries target specific records. Choose Redshift when analytical queries scan wide tables or require petabyte-scale storage.
- Architecture tradeoff: Redshift's columnar storage and massively parallel processing architecture deliver faster performance on analytical queries but sacrifice the indexing and strict constraint enforcement that Postgres provides.
- Operational overhead: Postgres offers lower operational complexity for teams without dedicated data engineers. Redshift requires active tuning of sort keys, distribution keys, and workload management queues.
- Analytics delivery: For teams that need governed analytics without warehouse management overhead, Domo connects to both systems and delivers outcomes through governed AI agents (with human-in-the-loop control), embedded analytics, and dashboards.
Postgres vs Redshift at a glance
This table summarizes the primary differences across the dimensions important to analytics teams.
What is PostgreSQL?
That number reflects both its reliability and the massive ecosystem of tools, extensions, and community knowledge surrounding it. The database uses row-oriented storage optimized for concurrent reads and writes, making it dependable for application backends.
It runs anywhere. Self-hosted servers, Amazon RDS, Google Cloud SQL, Azure. Pick your environment.
Postgres handles analytical queries at smaller scales through indexes, materialized views, and query optimization. But here's where the limitation surfaces: when queries scan large portions of tables. A row-store architecture reads entire rows from disk even when a query only needs a single column. That creates significant bottlenecks as tables grow.
You might discover this the hard way. Run an EXPLAIN plan on your most common reporting query. If sequential scans dominate your execution time, the database is reading too much unnecessary data.
Postgres provides several core capabilities that make it a default choice for application backends:
- Multi-version concurrency control: Enables concurrent transactions without locking the database for other operations.
- Indexes: Supports multiple index types for fast lookups, including generalized inverted indexes for text search.
- Binary JSON: Provides native semi-structured data support with indexing capabilities.
- Extensions: Allows custom functionality like spatial data processing or time-series optimization.
- Replication: Supports streaming replication to create read-only copies of the primary database.
What is Amazon Redshift?
Teams often assume Redshift operates exactly like Postgres because it shares similar SQL syntax. That assumption breaks down quickly.
Redshift is a columnar data warehouse with fundamentally different performance characteristics from Postgres. The system distributes data across multiple compute nodes, stores that data in columns rather than rows, and compresses it aggressively. Fast for queries that aggregate large datasets. Slower for point lookups and transactional patterns.
The platform has expanded from its original architecture to offer multiple deployment models:
- Provisioned clusters: The original model where teams pay for node-hours whether queries run or not.
- Separated compute and storage: Advanced nodes that allow teams to scale compute power independently from storage capacity.
- Redshift Serverless: A model that charges per query using processing units, eliminating cluster management entirely.
- Spectrum: A feature that queries data directly in cloud storage buckets without loading it into the warehouse first.
Redshift uses SQL syntax derived from an older version of PostgreSQL, but many familiar features behave differently. Foreign keys exist in the syntax but the system doesn't enforce them during data insertion. Traditional indexes? They don't exist at all.
Here's an operational hurdle that catches people off guard: teams migrate existing Postgres schemas directly to Redshift without defining distribution keys. Uneven data distribution forces one node to do all the work while the others sit idle, and you will pay for compute capacity that contributes nothing to query performance.
{{custom-cta-1}}
Postgres vs Redshift: Key differences
Comparing these two systems requires looking at five specific dimensions: storage and performance, scaling approaches, SQL compatibility, data types, and pricing.
Storage and performance
Assuming one database is universally faster than another leads to poor architectural decisions. This mistake shows up often in evaluations.
Postgres is faster for point lookups and small result sets. Redshift is faster for large aggregations and full-table scans. The gap can be orders of magnitude, not marginal improvements.
Postgres uses a row-store architecture that reads entire rows from disk, even when a query only references one column. Indexes make point lookups fast by pointing exactly to the required row. Aggregations over large tables force the system to perform sequential scans, reading massive amounts of irrelevant data.
Redshift uses columnar storage that reads only the columns a query references. Zone maps track the minimum and maximum values in each data block, allowing the system to skip blocks that can't contain matching values. But zone maps only help when data is physically sorted by the columns you're filtering on. Without proper sort keys, the system still scans more blocks than necessary.
Consider two query patterns. A query requesting a specific order by ID is typically a strong fit for Postgres with a standard index. Redshift often does more work for that pattern unless the data is sorted appropriately. On the other hand, a query that groups revenue by region across a very large table often forces Postgres into broad scans, while Redshift can distribute the aggregation across nodes and scan only the referenced columns.
Scaling approaches
When queries start slowing down, the path forward depends on whether the bottleneck is storage, compute, or concurrency.
Postgres scaling options include vertical scaling to larger instances, read replicas to offload read queries, partitioning to split large tables by date or category, and sharding to distribute data across multiple databases. Sharding requires significant application logic changes. Not a weekend project.
Redshift scaling options include cluster resize to add nodes, elastic resize for faster node changes, concurrency scaling to automatically add transient clusters during demand spikes, and serverless to scale processing units based on active query load.
Bursty workload with long idle periods? Redshift Serverless avoids paying for unused capacity. Steady and predictable workload? Reserved capacity on provisioned clusters costs less over time. If Postgres queries slow down due to table size, partitioning or materialized views often solve the problem before a full warehouse migration becomes necessary.
SQL compatibility
Redshift's PostgreSQL heritage leads teams to assume their existing queries will work unchanged. Many basic queries do execute perfectly, but structural differences cause migration failures.
Queries relying heavily on indexes need rewriting to use sort keys effectively. Applications depending on the database to enforce foreign key constraints need application-level validation added to the data pipeline (this catches many teams off guard during migration). Extensions used for spatial data or fuzzy text matching have no direct Redshift equivalent.
Data types and features
Both systems handle standard text, numeric, and date formats identically. They diverge in how they manage semi-structured data.
Postgres handles semi-structured data using a binary JSON format that supports indexing, making it fast for queries that filter deeply nested JSON fields. Redshift uses a specific semi-structured type for nested data that integrates with its columnar storage but doesn't support traditional indexing.
Both databases support materialized views to pre-calculate complex query results. Redshift refreshes these views faster on massive datasets due to its columnar architecture. Redshift also offers late-binding views that reference external tables in cloud storage, resolving their schema at query time rather than during creation.
Heavy JSON querying with specific filters? Postgres performs better. JSON data primarily stored for occasional extraction alongside structured data? Redshift handles it efficiently.
Pricing and cost
Comparing list prices without accounting for utilization patterns, data transfer fees, and operational overhead leads to budget overruns.
Postgres pricing factors: instance costs, storage costs, data transfer fees, and operational overhead for patching, backups, and monitoring.
Redshift pricing factors: node-hours for provisioned clusters or processing units for serverless deployments, managed storage costs billed separately from compute, scanning costs for querying data directly in cloud storage, and concurrency scaling charges.
Redshift requires a dedicated tuning investment. Skip sort key and distribution key optimization and you'll pay for that oversight in degraded query performance and higher concurrency scaling costs.
{{custom-cta-2}}
Should you choose Postgres or Redshift?
The choice between these systems is rarely binary.
Many organizations run Postgres as their transactional system and Redshift as their analytical layer, connecting the two through data pipelines.
Choose Postgres when data volume stays under a few hundred gigabytes, queries primarily target specific records via indexed lookups, the team lacks dedicated data engineering resources, or the workload mixes transactional writes with light analytics.
Choose Redshift when analytical queries scan large tables or aggregate across millions of rows, data volume exceeds what a single Postgres node handles efficiently, the team can invest in sort key and distribution key optimization, or BI tools require sub-second response times on complex queries.
Consider using both when Postgres handles the application database for transactional workloads and data pipelines replicate data to Redshift for analytical workloads. This architecture separates the workloads entirely, avoiding query contention on the production system.
If data volumes are small and query patterns are simple? Adding Redshift introduces operational complexity without proportional benefit. Start with Postgres and migrate analytical workloads only when performance degrades.
Consider Domo when the goal is governed analytics delivery rather than warehouse management, when data lives in Postgres, Redshift, or dozens of other sources that need unification, or when the team wants to operationalize insights through dashboards, AI agents, or embedded analytics without building new infrastructure.
Why Domo deserves consideration
Postgres and Redshift store and query data well, but neither system delivers governed analytics to the people who need to act on it. Building that delivery layer requires additional tooling, custom integration work, and constant maintenance. It's a lot.
Domo bridges that gap by connecting to Postgres, Redshift, and hundreds of other data sources, then delivering insights directly through the channels where daily work happens.
Domo provides a complete layer for data activation:
- Data integration: Pre-built connectors link to Postgres, Redshift, cloud data platforms, and software applications without requiring custom pipelines.
- Governed analytics: Role-based access controls carry from data ingestion through dashboards to AI agents.
- Dashboards and apps: Visualizations can refresh on a schedule or near real time, based on the source system and connector settings.
- AI agents: Conversational interfaces work on governed data with bounded autonomy, people set objectives and constraints, and teams review outputs or approve actions as needed (human in the loop).
- Embedded analytics: Deliver insights directly into customer portals, partner applications, or internal tools.
Domo is an agentic platform for the intelligent enterprise, unified by design and modular by adoption. It runs on top of your existing cloud data platform rather than replacing it. For teams that already have a warehouse, Domo can help more business people act on governed data through agent-driven workflows, embedded analytics, and dashboards. For teams evaluating warehouse options, Domo reduces the urgency by handling the analytics delivery layer regardless of which storage system sits underneath.
If you're ready to connect Postgres and Redshift (and everything else) into one governed layer for AI-driven outcomes, get a demo to see how bounded, human-in-the-loop agents, embedded analytics, and dashboards can fit into daily workflows.